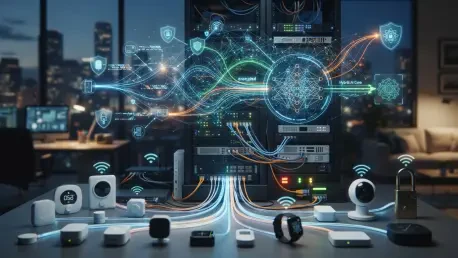
Researchers have developed a hybrid bio-inspired algorithm called Cheetah–Lyrebird Optimization to solve the complex engineering challenge of balancing data security with machine learning utility. As the digital ecosystem expands throughout 2026, the proliferation of the Internet of Things has fundamentally altered the landscape of personal data management, creating a world where connectivity is ubiquitous but vulnerability is constant. With the number of connected devices—ranging from specialized medical monitors to ubiquitous smart home sensors—projected to exceed tens of billions by 2030, the sheer volume of sensitive information in transit has reached a critical threshold. A study published in the International Journal of Machine Learning and Cybernetics by G. Uma Maheshwari and colleagues addresses this escalating crisis. Their research introduces a sophisticated privacy-preserving framework designed to secure IoT datasets without sacrificing their analytical value or clinical relevance in the healthcare research field.
Navigating the Privacy-Utility Tension
Structural Methods: Balancing Privacy and Utility
The fundamental difficulty in modern IoT data management lies in what engineers call the “privacy-utility trade-off,” a delicate balance between protection and usefulness. To protect an individual, data must be obscured or altered; however, if the data is obscured too heavily, it becomes functionally useless for training the artificial intelligence models that power modern healthcare and smart infrastructure. If a dataset is stripped of too much detail, it loses the subtle “signal” that algorithms need to identify trends or predict medical emergencies. Conversely, if the data is left in a relatively raw state, it becomes highly vulnerable to linkage attacks. In these scenarios, malicious actors cross-reference anonymized records with other public databases to re-identify specific individuals. Balancing these two competing needs is not merely a technical preference but an essential requirement for the sustainable growth of smart city infrastructure and personalized medicine in the coming years.
Categorical Integrity: Protecting Specific Data Types
To address the diverse risks inherent in large-scale data collection, the framework categorizes IoT information into three distinct levels: direct identifiers, quasi-identifiers, and sensitive attributes. Direct identifiers, such as names or specific social security numbers, are typically removed at the source to prevent immediate recognition. However, quasi-identifiers like age, gender, or general location pose a more insidious threat because they can be combined to uniquely pinpoint a person. Finally, sensitive attributes, such as specific medical diagnoses or private lifestyle habits, must remain strictly confidential even if the identity of the person is obscured. The study proposes a pipeline that treats each category with a different level of rigor: stripping identifiers, pseudonymizing quasi-identifiers using models like k-anonymity, and encrypting sensitive attributes with keys generated through advanced optimization. This ensures that the overall coherence of the data remains intact for researchers.
Biomimicry in Computational Security
Cheetah Mechanics: Broad Search for Security Keys
The most significant contribution of this research is the development of the Cheetah–Lyrebird Optimization (Ch-LbO) algorithm, which addresses the challenge of key generation in encryption. Finding an optimal encryption key—one that maximizes security while ensuring the data can still be processed—is an optimization problem with a nearly infinite search space. To navigate this, the researchers fused two metaheuristic models inspired by the natural world. The Cheetah Optimizer, inspired by the hunting tactics of the world’s fastest land animal, focuses on the “exploration” phase of the computational search. It models the coordinated behavior of cheetah coalitions, utilizing specific phases of searching, sitting-and-waiting, and stalking. This allows the system to scan vast areas of potential mathematical solutions efficiently. By mimicking the speed and strategic positioning of these predators, the algorithm can identify promising security configurations that might be missed by more rigid, traditional methods.
Lyrebird Precision: Refining Local Optimal Solutions
Complementing the broad reach of the cheetah is the Lyrebird Optimization Algorithm, which mimics the Australian lyrebird’s uncanny ability to learn and reproduce complex sounds with high fidelity. In the context of data science, this specialized behavior represents “exploitation”—the ability to zoom in on a promising area of the search space and refine it with extreme precision. While the cheetah identifies the general region of the best solution, the lyrebird component mimics the most successful patterns to hone the encryption parameters. This hybrid approach allows the Ch-LbO system to avoid the common pitfall of getting stuck in “local optima,” where a system settles for a good solution while missing the best possible one. By combining these two distinct evolutionary strategies, the framework converges on highly robust encryption configurations that are specifically tailored to the unique statistical distribution of the IoT dataset, ensuring both security and machine learning utility.
Validating Performance with Real-World Data
Dataset Validation: Testing in Medical Environments
To prove the efficacy of their framework, the researchers conducted extensive testing against four diverse, real-world IoT healthcare datasets: Blood Pressure, Body Performance, Heart Failure, and Smoker Status Prediction. These datasets are representative of the continuous physiological streams generated by modern wearable devices and remote patient monitoring systems. Testing on such varied data was crucial because it demonstrated the algorithm’s versatility across different types of medical signals, from categorical binary data to complex numerical ranges. The researchers applied their multi-tiered privacy pipeline to these datasets and then ran the resulting “anonymized” records through various machine learning classifiers. This step was designed to see if the data could still predict health outcomes accurately despite the heavy encryption and pseudonymization. The use of real-world clinical data ensured that the results were not just theoretically sound but practically applicable in the healthcare sector.
Statistical Evidence: Accuracy and Reliability Metrics
The empirical results from the testing phase were statistically significant and demonstrated a high level of consistency across all four datasets. Across the various machine learning models used for validation, the privacy-protected data maintained predictive accuracy between 88.89% and 99.54%. Precision and recall figures were equally impressive, frequently exceeding the 99% mark in several specific testing scenarios. These metrics are vital because they provide concrete proof that the anonymization process did not destroy the underlying “signal” or the predictive power within the data. Even though the individual records were thoroughly protected against re-identification, the core medical patterns remained visible to the artificial intelligence. This allows healthcare providers to function at a level nearly identical to their performance on unprotected, raw data, proving that high-security standards do not have to come at the expense of life-saving medical insights or diagnostic precision.
Security Benchmarks and Regulatory Compliance
Quantifiable Gains: Improving Data Modification Rates
In addition to accuracy, the study focused on the “Data Modification Rate,” a metric that quantifies how thoroughly a system alters records to thwart re-identification attempts. On the Body Performance dataset, the Ch-LbO framework achieved an 81.9% improvement over existing state-of-the-art methods, representing a major leap in protective capabilities. Furthermore, the researchers analyzed the “Correlation Coefficient” between the original raw data and the protected output. They found a remarkably low correlation of only 0.12% to 0.34%, indicating that an adversary looking at the protected records would find almost no statistical link to the original identities. However, because the overarching distributions and relationships between variables were preserved, legitimate analysts could still draw valid conclusions. This highlights the framework’s ability to transform the quasi-identifier space into a secure zone without eroding the coherence or the scientific integrity of the original information.
Strategic Integration: Moving Toward Intelligent Security
The study by Maheshwari and colleagues established a new benchmark for privacy-preserving technology in the era of pervasive IoT connectivity. By successfully integrating statistical pseudonymization with the hybrid Cheetah–Lyrebird Optimization, the researchers demonstrated that it was possible to achieve near-total privacy protection while maintaining the high utility of clinical data. The project concluded that bio-inspired metaheuristics offered a superior pathway for managing the complexity of modern cybersecurity. For future implementation, organizations should focus on adapting these automated optimization engines to handle real-time streaming data, which arrives in constant, never-ending flows from millions of devices. Furthermore, testing these systems against adaptive adversaries who use their own AI to reverse-engineer anonymization will be a critical next step. This research provides a robust template for the next generation of secure, intelligent, and privacy-conscious data ecosystems across various global industries.